← Back to open sourceFeatured starting point
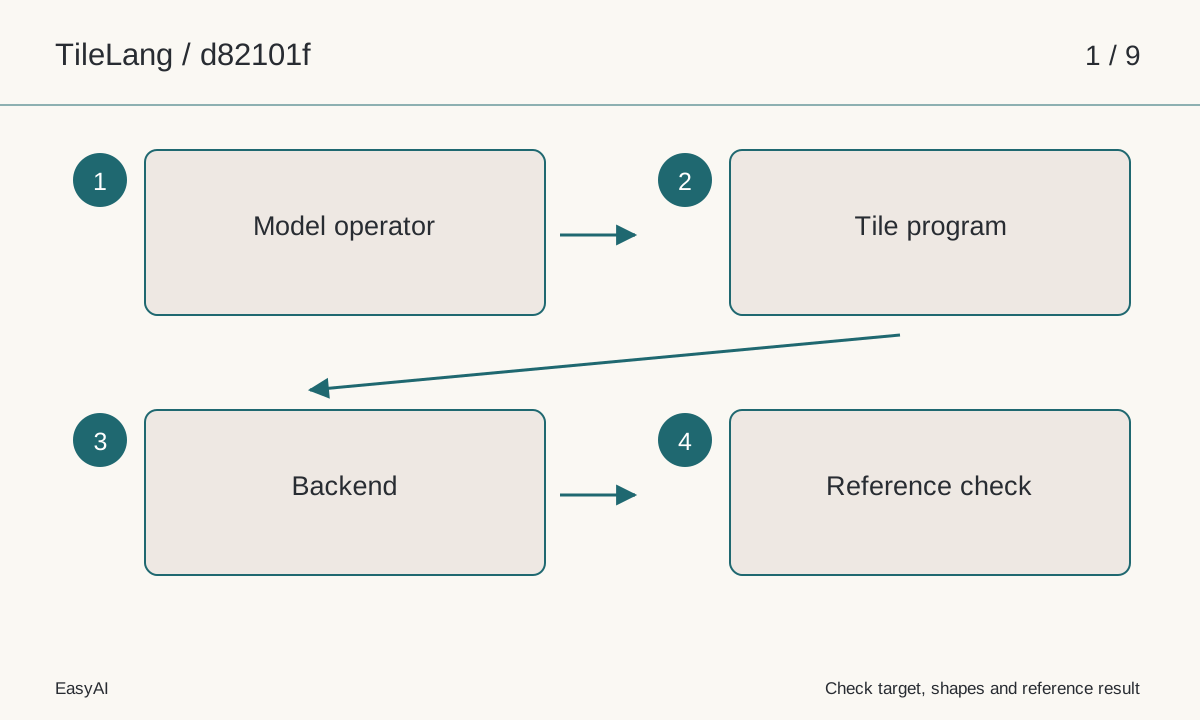
See where the Python DSL sits between model code and device-specific execution
TileLang explained: write AI kernels at tile granularityTileLangtile-ai/tilelang
Start reading →Suggested learning path
01 → 09
01·3 min read·Search intent: Learning
See where the Python DSL sits between model code and device-specific execution
TileLang explained: write AI kernels at tile granularityTileLangtile-ai/tilelang
·3 min read·Search intent: Learning
Set up one supported device and verify output before tuning tile sizes
TileLang quickstart: a GEMM kernel with a correctness gateTileLangtile-ai/tilelang
·3 min read·Search intent: Learning
Move a verified operator into an inference or training service without surprising rebuilds
Deploying TileLang kernels: pin the toolchain and targetTileLangtile-ai/tilelang
·3 min read·Search intent: Learning
Trace the DSL, JIT specialization and backend choices without treating one GPU as universal
TileLang architecture: from Python tiles to a device kernelTileLangtile-ai/tilelang
·3 min read·Search intent: Learning
Use the public example and JIT entry point as an auditable path through the repository
TileLang source-code analysis: where GEMM becomes a compiled callTileLangtile-ai/tilelang
·3 min read·Search intent: Learning
Separate compilation, warm execution, correctness and service-level value
TileLang performance and cost: benchmark the whole kernel lifecycleTileLangtile-ai/tilelang
·3 min read·Search intent: Learning
Treat compiler inputs, device runtimes and shape-dependent failures as operational concerns
TileLang security and operations: JIT code is a deployment dependencyTileLangtile-ai/tilelang
·3 min read·Search intent: Learning
Pick the least costly route that meets correctness and throughput requirements
Choosing TileLang: tile DSL, framework operator or low-level kernelTileLangtile-ai/tilelang
·3 min read·Search intent: Learning
Move from a passing README example to evidence for one real model bottleneck
TileLang next steps: a controlled operator pilotTileLangtile-ai/tilelang