
pdf-inspector
Arquitectura de pdf-inspector: detección, layout, tablas y OCR
Una carga, tipos intermedios, Markdown y ruta OCR selectiva.

Qué aprenderás
- Trace detection and layout stages
- Run native extraction and OCR safely
- Design provenance checks
Antes de empezar
- Basic Git and command-line usage
- Comfort reading a project README
You can explain the project, run its documented first step, and decide what to verify before adopting it.
Conclusiones clave
- Detection and extraction share one parsed document.
- Layout and tables are explicit intermediate stages.
- OCR is a governed side path with provenance.
Single-load pipeline
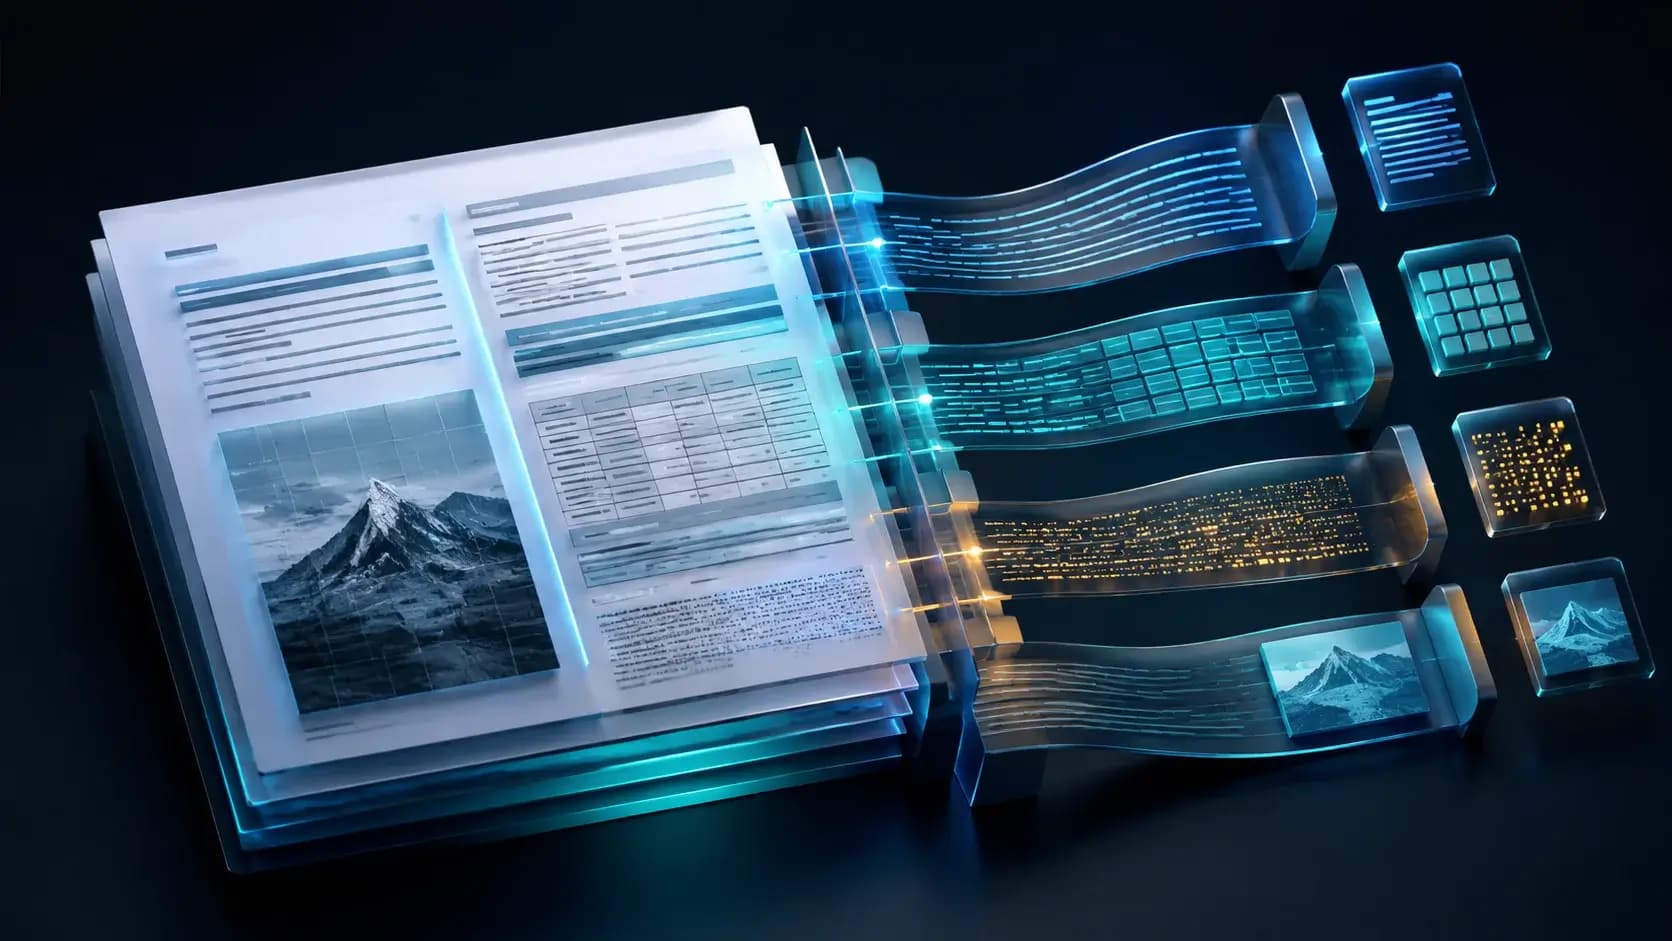
Detección y extracción comparten documento; items y rectángulos pasan por columnas, tablas y Markdown, y las páginas anómalas salen a OCR.
Use the pinned source evidence, record versions and assumptions, and ask a qualified reviewer to validate the result before adopting it.
Structure recovery
Column detection and line grouping feed heading, list, code, caption and table classifiers. Rectangle and alignment heuristics produce grids that the Markdown stage formats.
OCR as a side path
Broken encodings or image pages are flagged and routed selectively. The OCR envelope preserves pages, confidence, warnings and hosted-fallback recommendations without changing the native path.
Use the pinned source evidence, record versions and assumptions, and ask a qualified reviewer to validate the result before adopting it.
Cómo elegir
| Criterio | Opción A | Opción B |
|---|---|---|
| Best when | You need predictable behavior and easy auditing | You need adaptive optimization and have reliable telemetry |
| Main risk | May leave performance on the table | Can become difficult to explain or debug |
Pasos de implementación
- 1
Map bytes to detector and loader.
- 2
Trace text items through layout and tables.
- 3
Inspect Markdown post-processing.
- 4
Follow routed pages into OCR and warnings.
Ejemplo para copiar
PDF bytes -> detector + single load
  -> content streams/fonts/xobjects -> TextItems/PdfRects
  -> layout -> tables -> Markdown
  -> selected pages -> OCR envelope
Preguntas frecuentes
Why parse a document once?
Shared state avoids redundant I/O and keeps detection, extraction, and provenance coherent.
How are tables detected?
The README describes rectangle-based and alignment-based heuristics feeding a grid formatter.
Fuentes
- pdf-inspector README (captured 2026-08-31)Fuente verificada 2026-08-31
- pdf-inspector repositoryFuente verificada 2026-08-31