
pdf-inspector
pdf-inspector 部署:Rust、Python、Node、WASM 与 OCR
选择本地、服务端或浏览器边界并保持 OCR 可选。
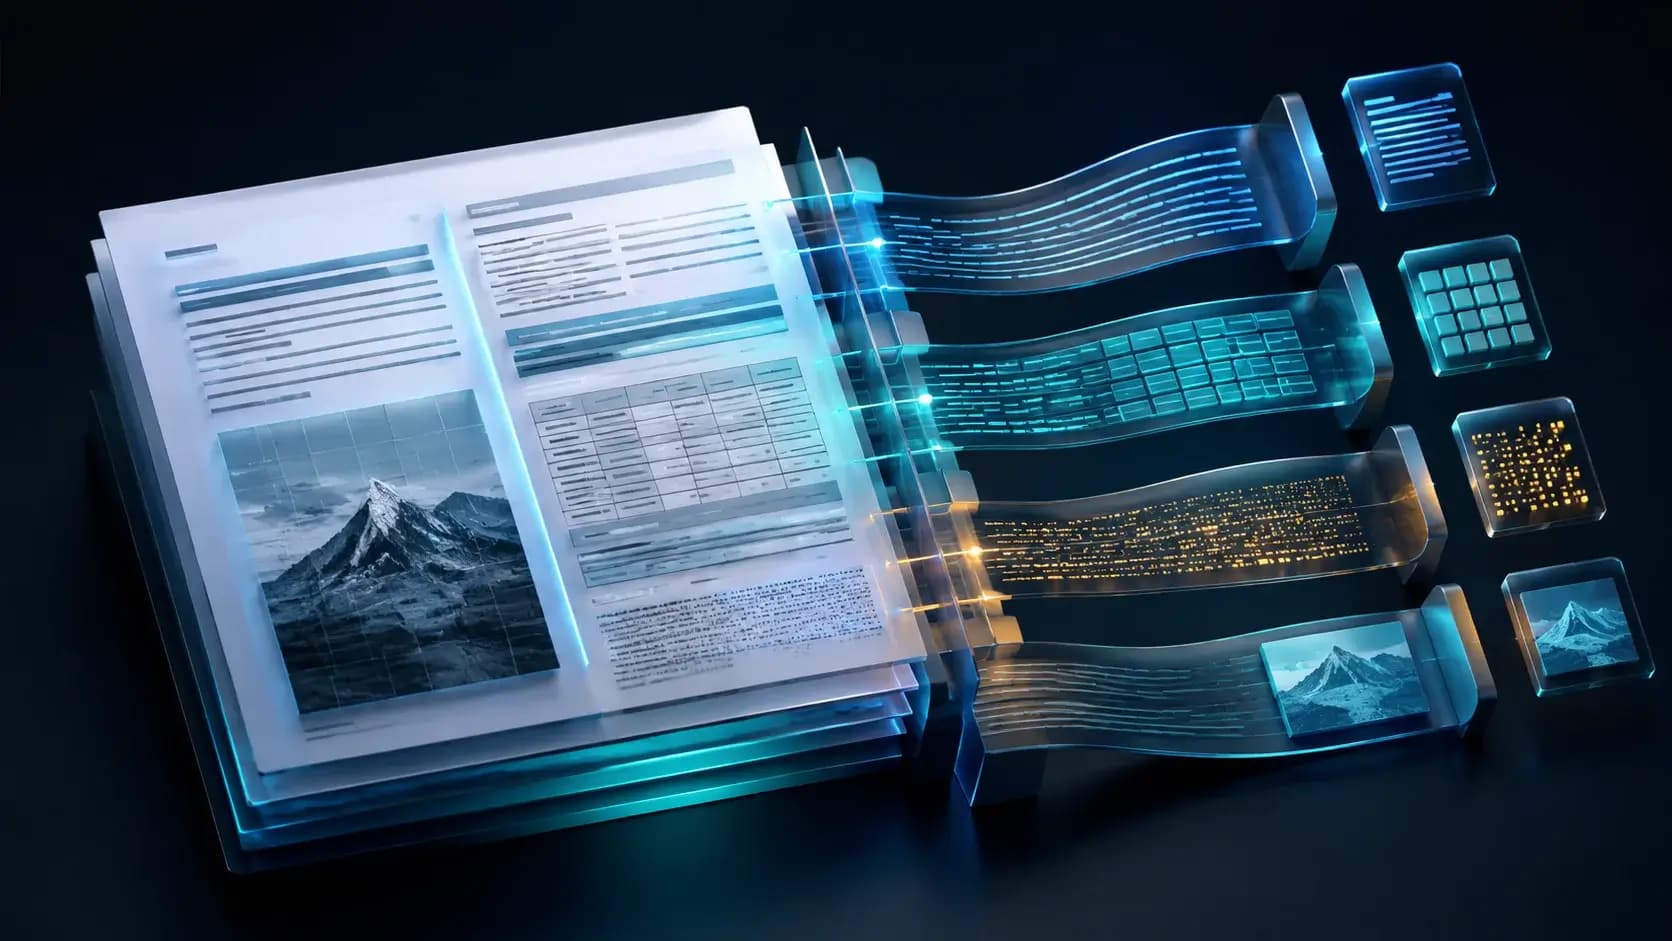

你将学会
- Trace detection and layout stages
- Run native extraction and OCR safely
- Design provenance checks
开始前需要
- Basic Git and command-line usage
- Comfort reading a project README
You can explain the project, run its documented first step, and decide what to verify before adopting it.
先看结论
- Deployment choice follows residency and runtime needs.
- OCR dependencies should not burden native-text paths.
- Malformed PDFs and missing runtimes need explicit errors.
Choose the boundary
按数据驻留选择 CLI、绑定或 WASM;只有 OCR worker 安装 PDFium、ONNX Runtime 和模型,并测试畸形文件与缺失依赖。
Use the pinned source evidence, record versions and assumptions, and ask a qualified reviewer to validate the result before adopting it.
Keep OCR optional
Default Rust/browser builds remain pure extraction. Native OCR needs separately installed PDFium, ONNX Runtime, and model files only when pages are routed; document those platform dependencies explicitly.
Operate
Pin crate/npm/PyPI versions, model caches, feature flags, and sample PDFs. Test malformed files, large pages, missing OCR libraries, worker cancellation, and disk cleanup before exposing a service.
Use the pinned source evidence, record versions and assumptions, and ask a qualified reviewer to validate the result before adopting it.
如何选择
| 比较维度 | 方案 A | 方案 B |
|---|---|---|
| Best when | You need predictable behavior and easy auditing | You need adaptive optimization and have reliable telemetry |
| Main risk | May leave performance on the table | Can become difficult to explain or debug |
实施步骤
- 1
Select CLI, binding, or WASM boundary.
- 2
Pin versions and optional OCR runtimes.
- 3
Run smoke and failure fixtures.
- 4
Monitor latency, memory, cache, and cleanup.
可复制示例
cargo install pdf-inspector
# OCR build only when needed
cargo install pdf-inspector --features ocr --bin pdf2md
PDFIUM_LIB_PATH=/path/to/libpdfium ORT_DYLIB_PATH=/path/to/libonnxruntime pdf2md scan.pdf --ocr auto --json
常见问题
Can browser WASM call PDFium?
The documented browser path uses the Rust parser and embedded CMaps; native OCR dependencies are a separate boundary.
Should OCR libraries be in every container?
No. Keep them in workers that actually receive routed pages.
资料来源
- pdf-inspector README (captured 2026-08-31)来源核查 2026-08-31
- pdf-inspector repository来源核查 2026-08-31