
pdf-inspector
pdf-inspector 安全与运维:把 PDF 当作不可信输入
隔离解析、限制资源、治理 OCR 外发和保留策略。
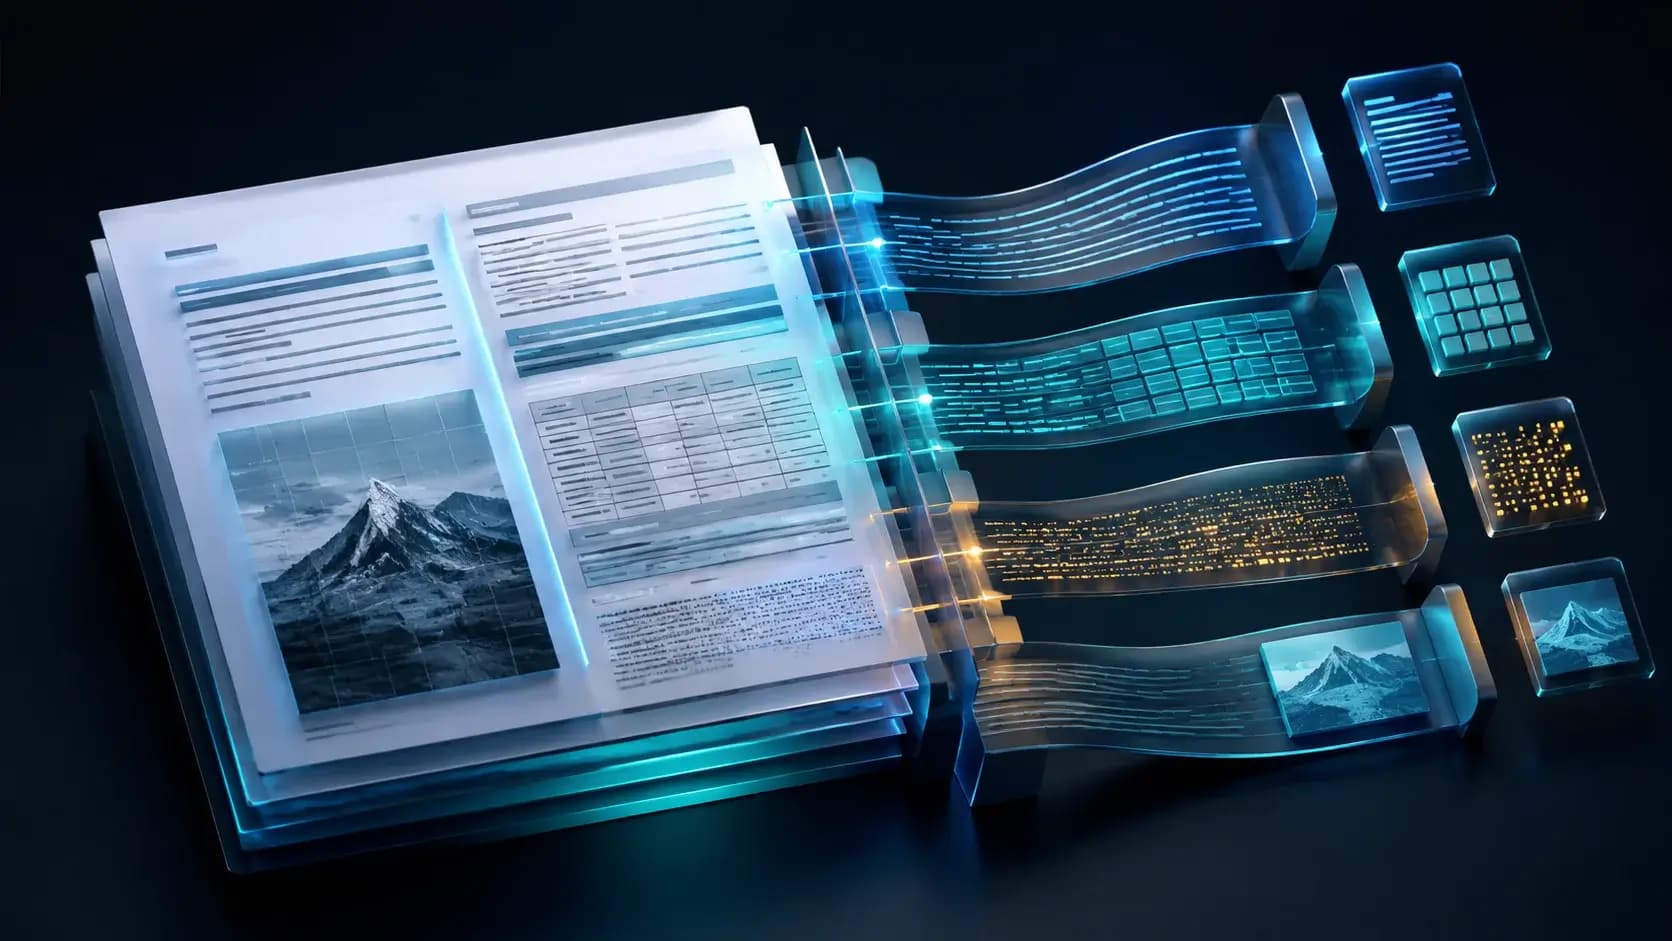

你将学会
- Trace detection and layout stages
- Run native extraction and OCR safely
- Design provenance checks
开始前需要
- Basic Git and command-line usage
- Comfort reading a project README
You can explain the project, run its documented first step, and decide what to verify before adopting it.
先看结论
- A PDF parser needs resource limits and isolation.
- Derived Markdown must retain page provenance.
- OCR fallback is an external data boundary.
Input isolation
畸形对象、链接、表单和超大页面进入沙箱,限制大小、页数、时间、内存与出站;Markdown 仍是派生数据并保留页级来源。
Use the pinned source evidence, record versions and assumptions, and ask a qualified reviewer to validate the result before adopting it.
OCR and fallback
Keep PDFium/ONNX workers separated, restrict model caches and outbound traffic, and make hosted fallback explicit. Store per-page source and confidence so downstream users can see uncertainty.
Retention and response
Encrypt originals and extracted text, redact logs, define deletion windows, and rehearse cancellation, quarantine, cleanup, and restore. Treat Markdown as derived data, not a replacement for the original evidence.
Use the pinned source evidence, record versions and assumptions, and ask a qualified reviewer to validate the result before adopting it.
如何选择
| 比较维度 | 方案 A | 方案 B |
|---|---|---|
| Best when | You need predictable behavior and easy auditing | You need adaptive optimization and have reliable telemetry |
| Main risk | May leave performance on the table | Can become difficult to explain or debug |
实施步骤
- 1
Define input, output, and retention policy.
- 2
Sandbox parser and OCR workers.
- 3
Restrict links, egress, and caches.
- 4
Monitor, quarantine, delete, and restore.
可复制示例
untrusted PDF -> sandbox limits -> parser
page evidence + confidence -> redacted Markdown
OCR/fallback -> approved egress + retention
incident -> stop/quarantine/delete/restore
常见问题
Can pdf-inspector safely fetch links inside a PDF?
The parser should extract links as data; fetching them requires a separate, authorized component with allow-lists.
Should extracted text be kept forever?
No. Match retention to purpose and preserve only the evidence needed for the workflow.
资料来源
- pdf-inspector README (captured 2026-08-31)来源核查 2026-08-31
- pdf-inspector repository来源核查 2026-08-31