
microduck_rl
microduck_rl Architecture: Environment, mjlab Physics, Rewards, and Policy Runner
Trace observations through actions, physics, reward shaping, termination, and policy updates in the Microduck loop.

What you will learn
- Map environment, simulator, and runner
- Run a reproducible simulation
- Identify sim-to-real gates
Before you start
- Basic Git and command-line usage
- Comfort reading a project README
You can explain the project, run its documented first step, and decide what to verify before adopting it.
Key takeaways
- Environment and runner are different responsibilities.
- Reward/termination define the task semantics.
- Transfer requires a runtime adapter and safety controls.
The control loop
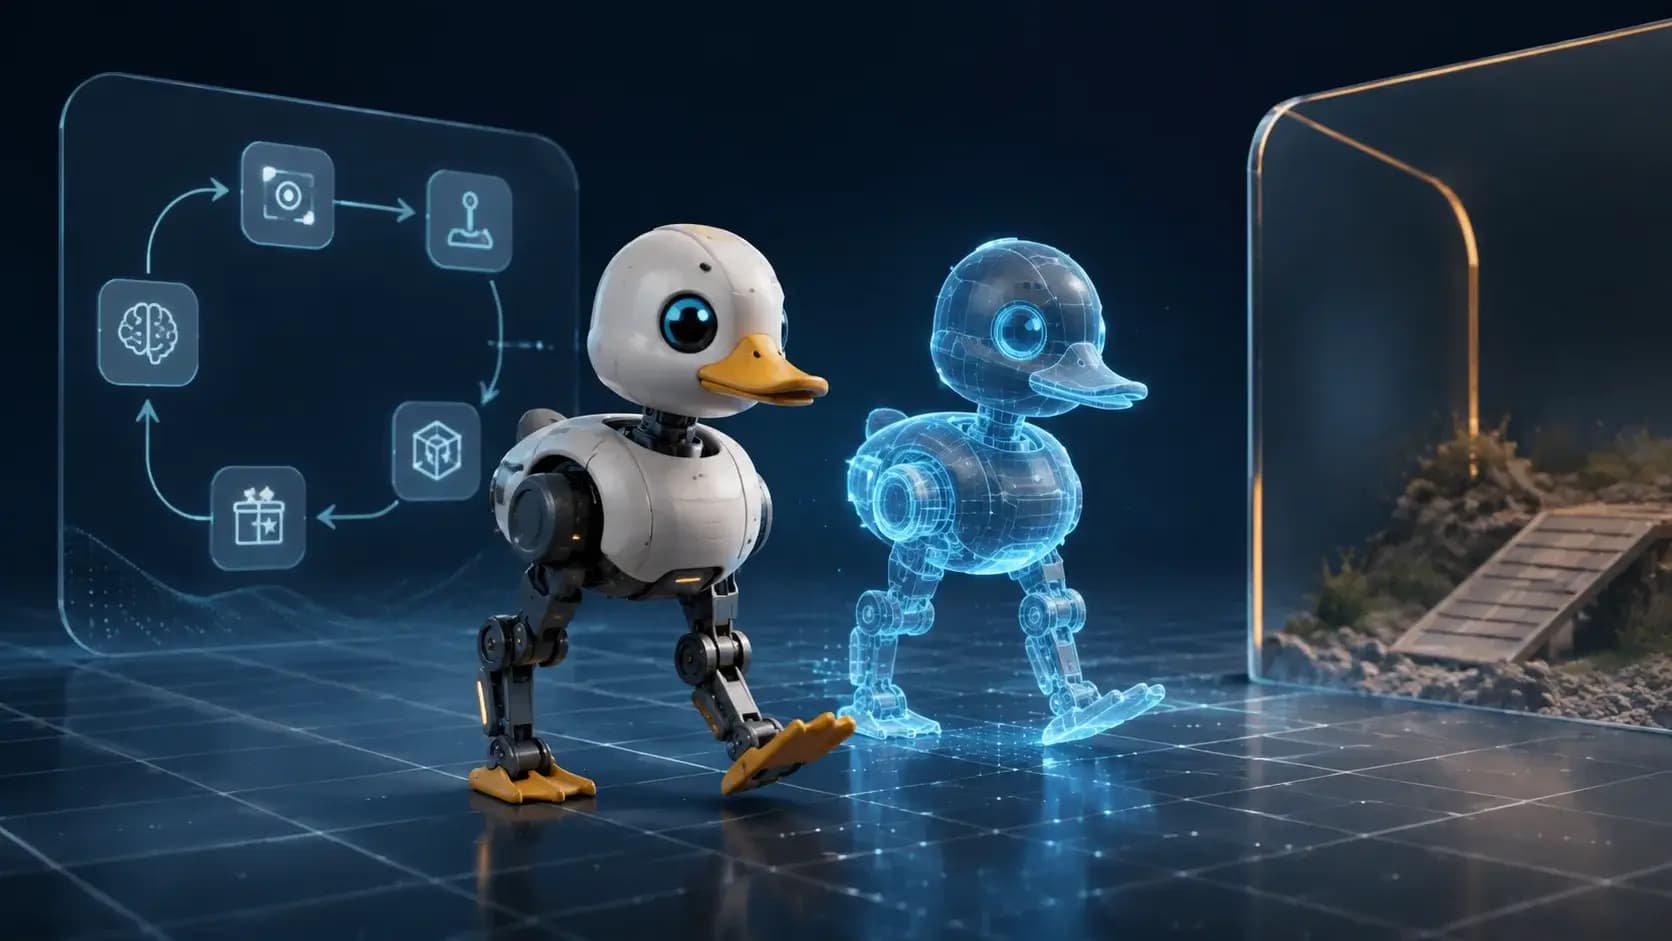
The core loop is observation → action → mjlab physics rollout → reward/termination → policy update. Keep environment adapters, simulator configuration, reward terms, and runner orchestration as separate contracts.
Use the pinned source evidence, record versions and assumptions, and ask a qualified reviewer to validate the result before adopting it.
Where behavior comes from
Task definitions, reset conditions, contacts, actuator limits, and randomization shape the data seen by the policy. Version each one because a reward change can invalidate a checkpoint comparison.
Transfer surface
Exported policies need a runtime adapter for control frequency, sensors, saturation, watchdogs, and fallback actions. Simulation and hardware telemetry should share a comparable schema.
Use the pinned source evidence, record versions and assumptions, and ask a qualified reviewer to validate the result before adopting it.
Decision guide
| Criterion | Option A | Option B |
|---|---|---|
| Best when | You need predictable behavior and easy auditing | You need adaptive optimization and have reliable telemetry |
| Main risk | May leave performance on the table | Can become difficult to explain or debug |
Implementation steps
- 1
Map environment and simulator interfaces.
- 2
Trace one action through physics and reward.
- 3
Version resets, randomization, and limits.
- 4
Define export and hardware adapter contracts.
Copy-ready example
obs -> policy -> action limits
    -> mjlab physics -> reward + done
    -> rollout buffer -> optimizer
    -> export adapter -> watchdog/hardware
Frequently asked questions
Can reward be changed after training?
Changing reward changes task semantics; treat it as a new experiment and checkpoint lineage.
Why keep termination explicit?
It affects data distribution, safety, and evaluation, so hidden termination logic makes runs incomparable.
Sources
- microduck_rl repositorySource checked 2026-08-31